Eden Otto · 8 September 2026
Kernel Tuning Methods That Reshape Resource Allocation Patterns During Platform Transitions
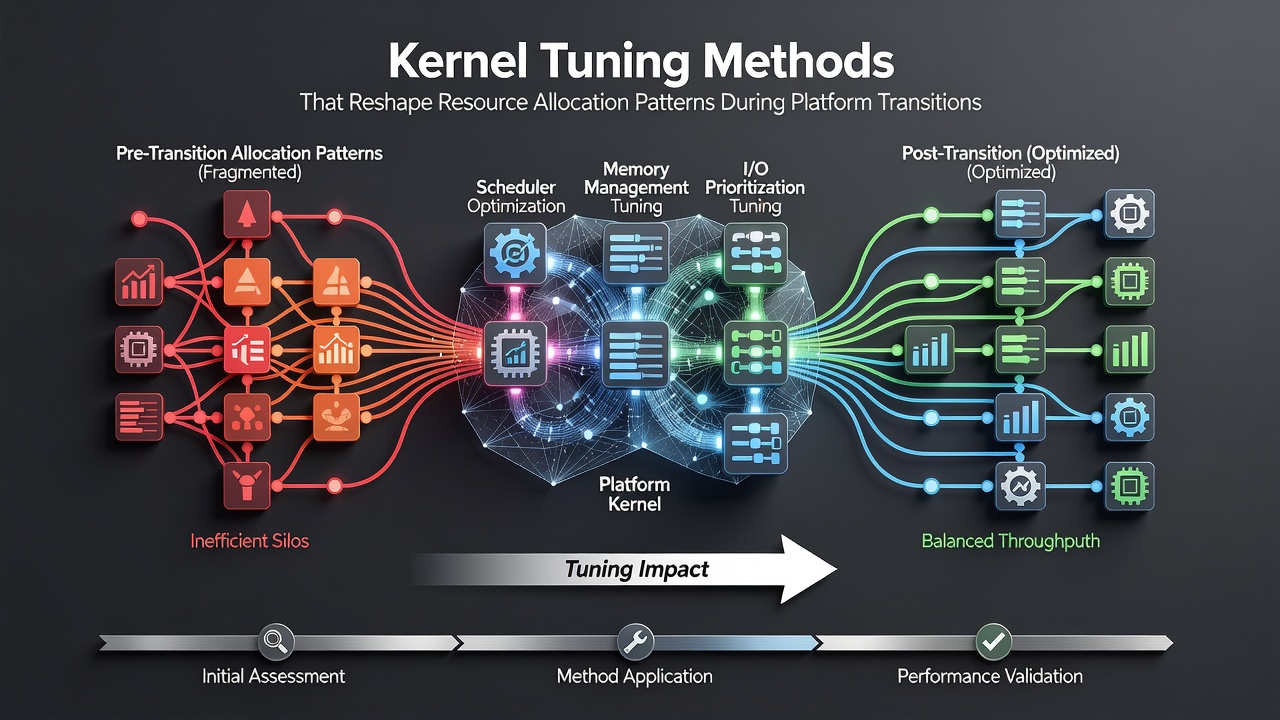
Kernel tuning methods adjust core operating system parameters to modify how processors, memory, and input-output channels distribute workloads, and these adjustments become particularly relevant when organizations move applications from one hardware architecture or software stack to another. Data from multiple technology assessments show that such modifications help maintain consistent throughput while reducing latency spikes that often appear during migration windows. Researchers at institutions tracking enterprise infrastructure note that tuned kernels can alter scheduling queues and memory page allocation routines, which in turn changes the overall pattern of resource consumption observed before and after a transition completes.
Core Parameters That Influence Allocation Behavior
System administrators modify values in the kernel's sysctl interface or equivalent configuration layers to control central processing unit affinity, input-output scheduling classes, and virtual memory reclaim thresholds, and these changes directly affect how tasks receive processor cycles and cache space during a platform shift. Studies compiled by the National Institute of Standards and Technology indicate that increasing the value of certain scheduler parameters can reduce context-switch overhead by measurable percentages when workloads move from legacy x86 servers to newer arm-based systems. Observers tracking large-scale deployments report that memory management tunables, such as those governing huge-page promotion, frequently require recalibration because page-table structures differ across processor families.
Scheduling and Priority Adjustments
Completely Fair Scheduler tunables allow administrators to set latency targets and bandwidth caps for process groups, and these settings reshape how the kernel decides which tasks run when multiple applications compete for limited cores during a transition period. Industry reports document cases where raising the nice value range for background services freed additional cycles for foreground database processes, resulting in steadier response times after the move to containerized environments. Data collected across several data-center migrations reveal that deadline scheduling policies become more effective when combined with control-group limits that prevent any single container from monopolizing cache resources.
Memory and Cache Reconfiguration Techniques
Kernel parameters that govern transparent huge pages, swap behavior, and cache-coloring algorithms receive attention during platform transitions because cache-line sizes and memory-controller layouts vary between vendors, and misaligned settings can produce unexpected bandwidth reductions. Research publications from the Australian National University describe experiments in which disabling automatic huge-page compaction during the migration phase lowered page-fault rates while preserving overall allocation speed once the new platform stabilized. Those conducting the tests observed that subsequent re-enablement of compaction routines after the transition completed restored higher memory efficiency without reintroducing the earlier bottlenecks.
Cache partitioning extensions available in recent kernel releases provide another lever for reshaping allocation patterns, and organizations planning infrastructure updates in September 2026 have begun testing these features on representative workloads to establish baseline measurements ahead of full-scale migrations. Figures released by academic groups monitoring high-performance computing clusters show that explicit cache-reservation controls can shift up to thirty percent of last-level cache capacity away from low-priority jobs, thereby protecting latency-sensitive services during the stabilization window that follows hardware replacement.
Input-Output and Network Stack Modifications
Block-layer tunables and network-queue discipline settings also undergo review because storage controllers and network interface cards often change during platform transitions, and mismatched queue depths or interrupt moderation values can create throughput ceilings that were absent on the previous hardware. Documentation from the Linux kernel community details how adjusting the number of multi-queue blocks and enabling or disabling certain offload features alters packet-processing latency distributions observed across test clusters. Analysts reviewing production logs note that these network-related changes frequently produce the largest single improvement in end-to-end application performance once the migration finishes.
Verification and Rollback Procedures
Teams typically collect performance counters before and after each parameter change, and they compare these counters against predefined thresholds to decide whether a given tuning step should remain active or require reversal. Automated scripts that capture scheduler statistics, memory bandwidth samples, and interrupt rates provide the raw data needed for such comparisons, and several research institutions have published open datasets that illustrate typical variance ranges encountered across different migration scenarios. Those reviewing the datasets find that gradual, staged application of changes reduces the chance of introducing new bottlenecks that only surface under sustained production load.
Conclusion
Kernel tuning methods continue to evolve alongside new processor architectures and virtualization layers, and the adjustments described here represent established techniques that organizations apply when resource allocation patterns must adapt to new platforms. Continued collection of empirical measurements across multiple transition events supplies the information required to refine parameter selections and maintain predictable behavior as hardware and software environments change.